


The Willow September 2026 digest blog
The Willow August Digest: Let Agents Act on Their Own. Govern Every Step.
Most of what shipped in Willow this August points the same direction. Agents are doing more without a person in the loop, and the controls had to grow up to match. A background agent that reconnects its own integrations, a model call that gets checked before it runs, a risk score that tightens access the moment it climbs: each one lets you hand off more of the work while keeping the same answer to "who approved this?" A few of these started as requests customers sent us directly. Here's what changed.
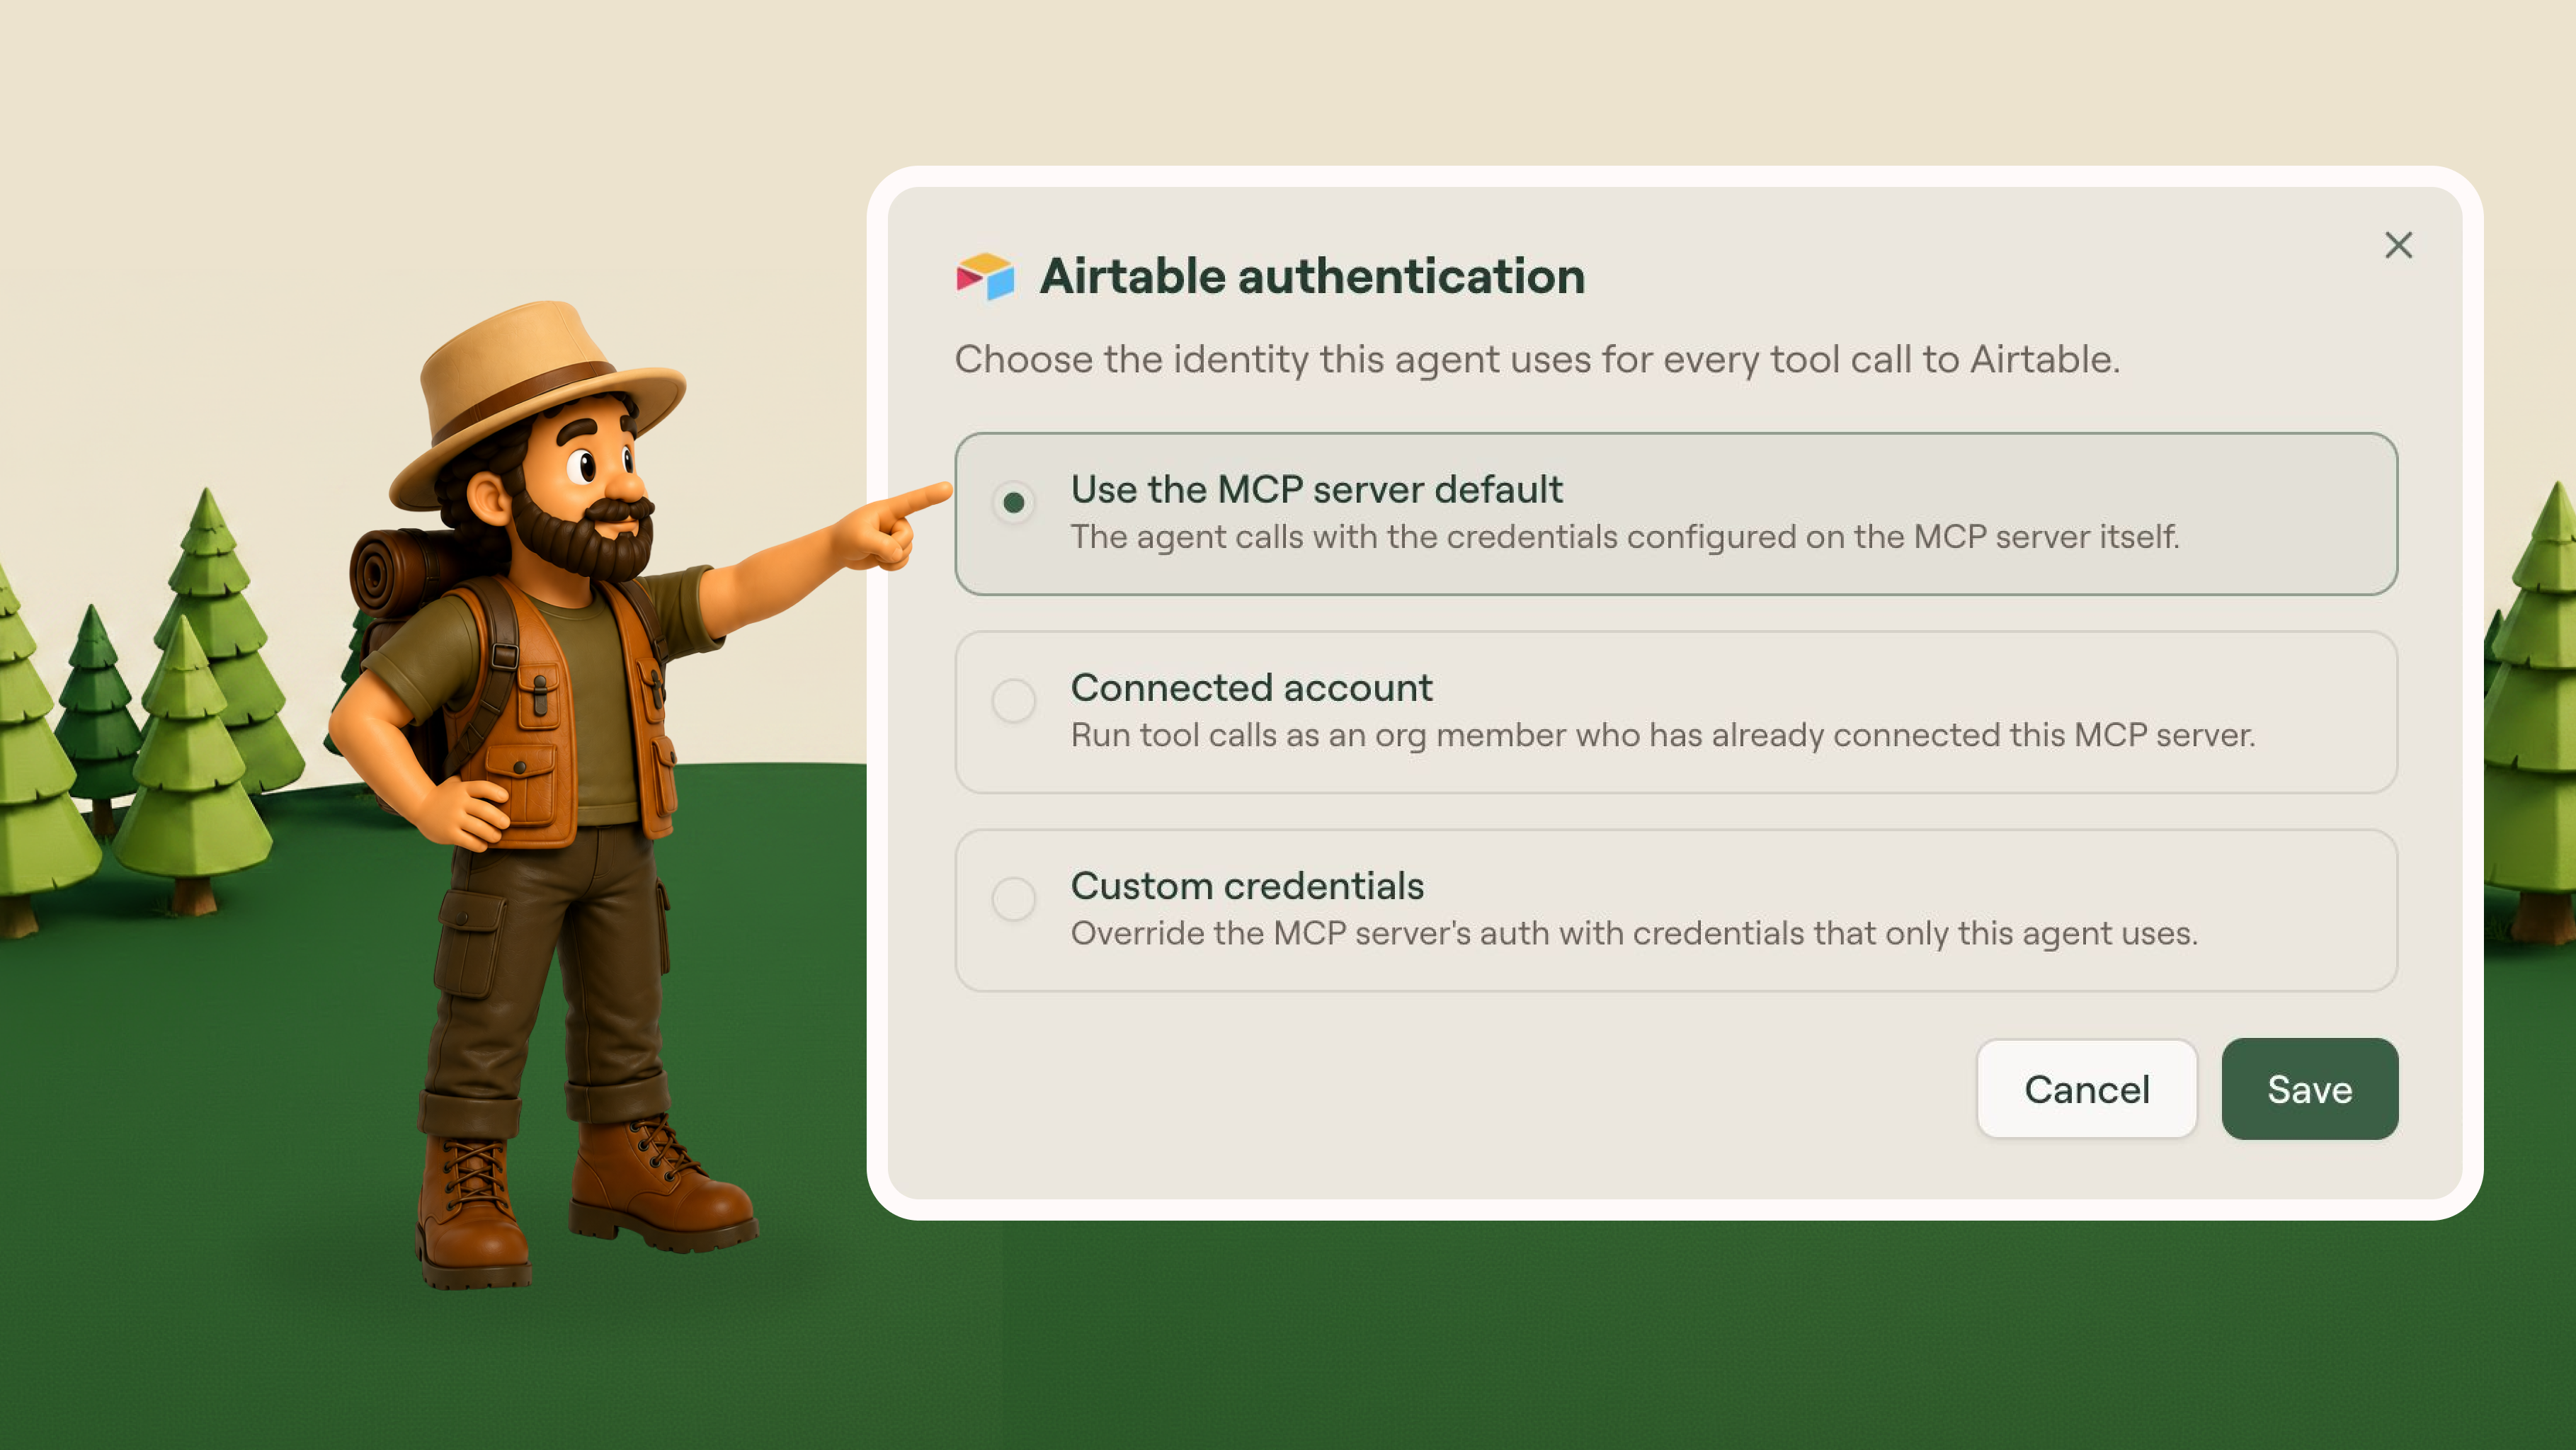
Guards now run on the model call itself. They used to stop at the tool call, which left the reasoning step as a blind spot: the model got to think before your policies got a say. That gap is closed. Every Anthropic inference request is now evaluated against your guards before it runs, so the model call is governed like everything else instead of sitting outside the perimeter. You turn it on from the Guards page, and it applies to every inference request from that point on. We ran it across our own workspace first. Enforce guards on inference
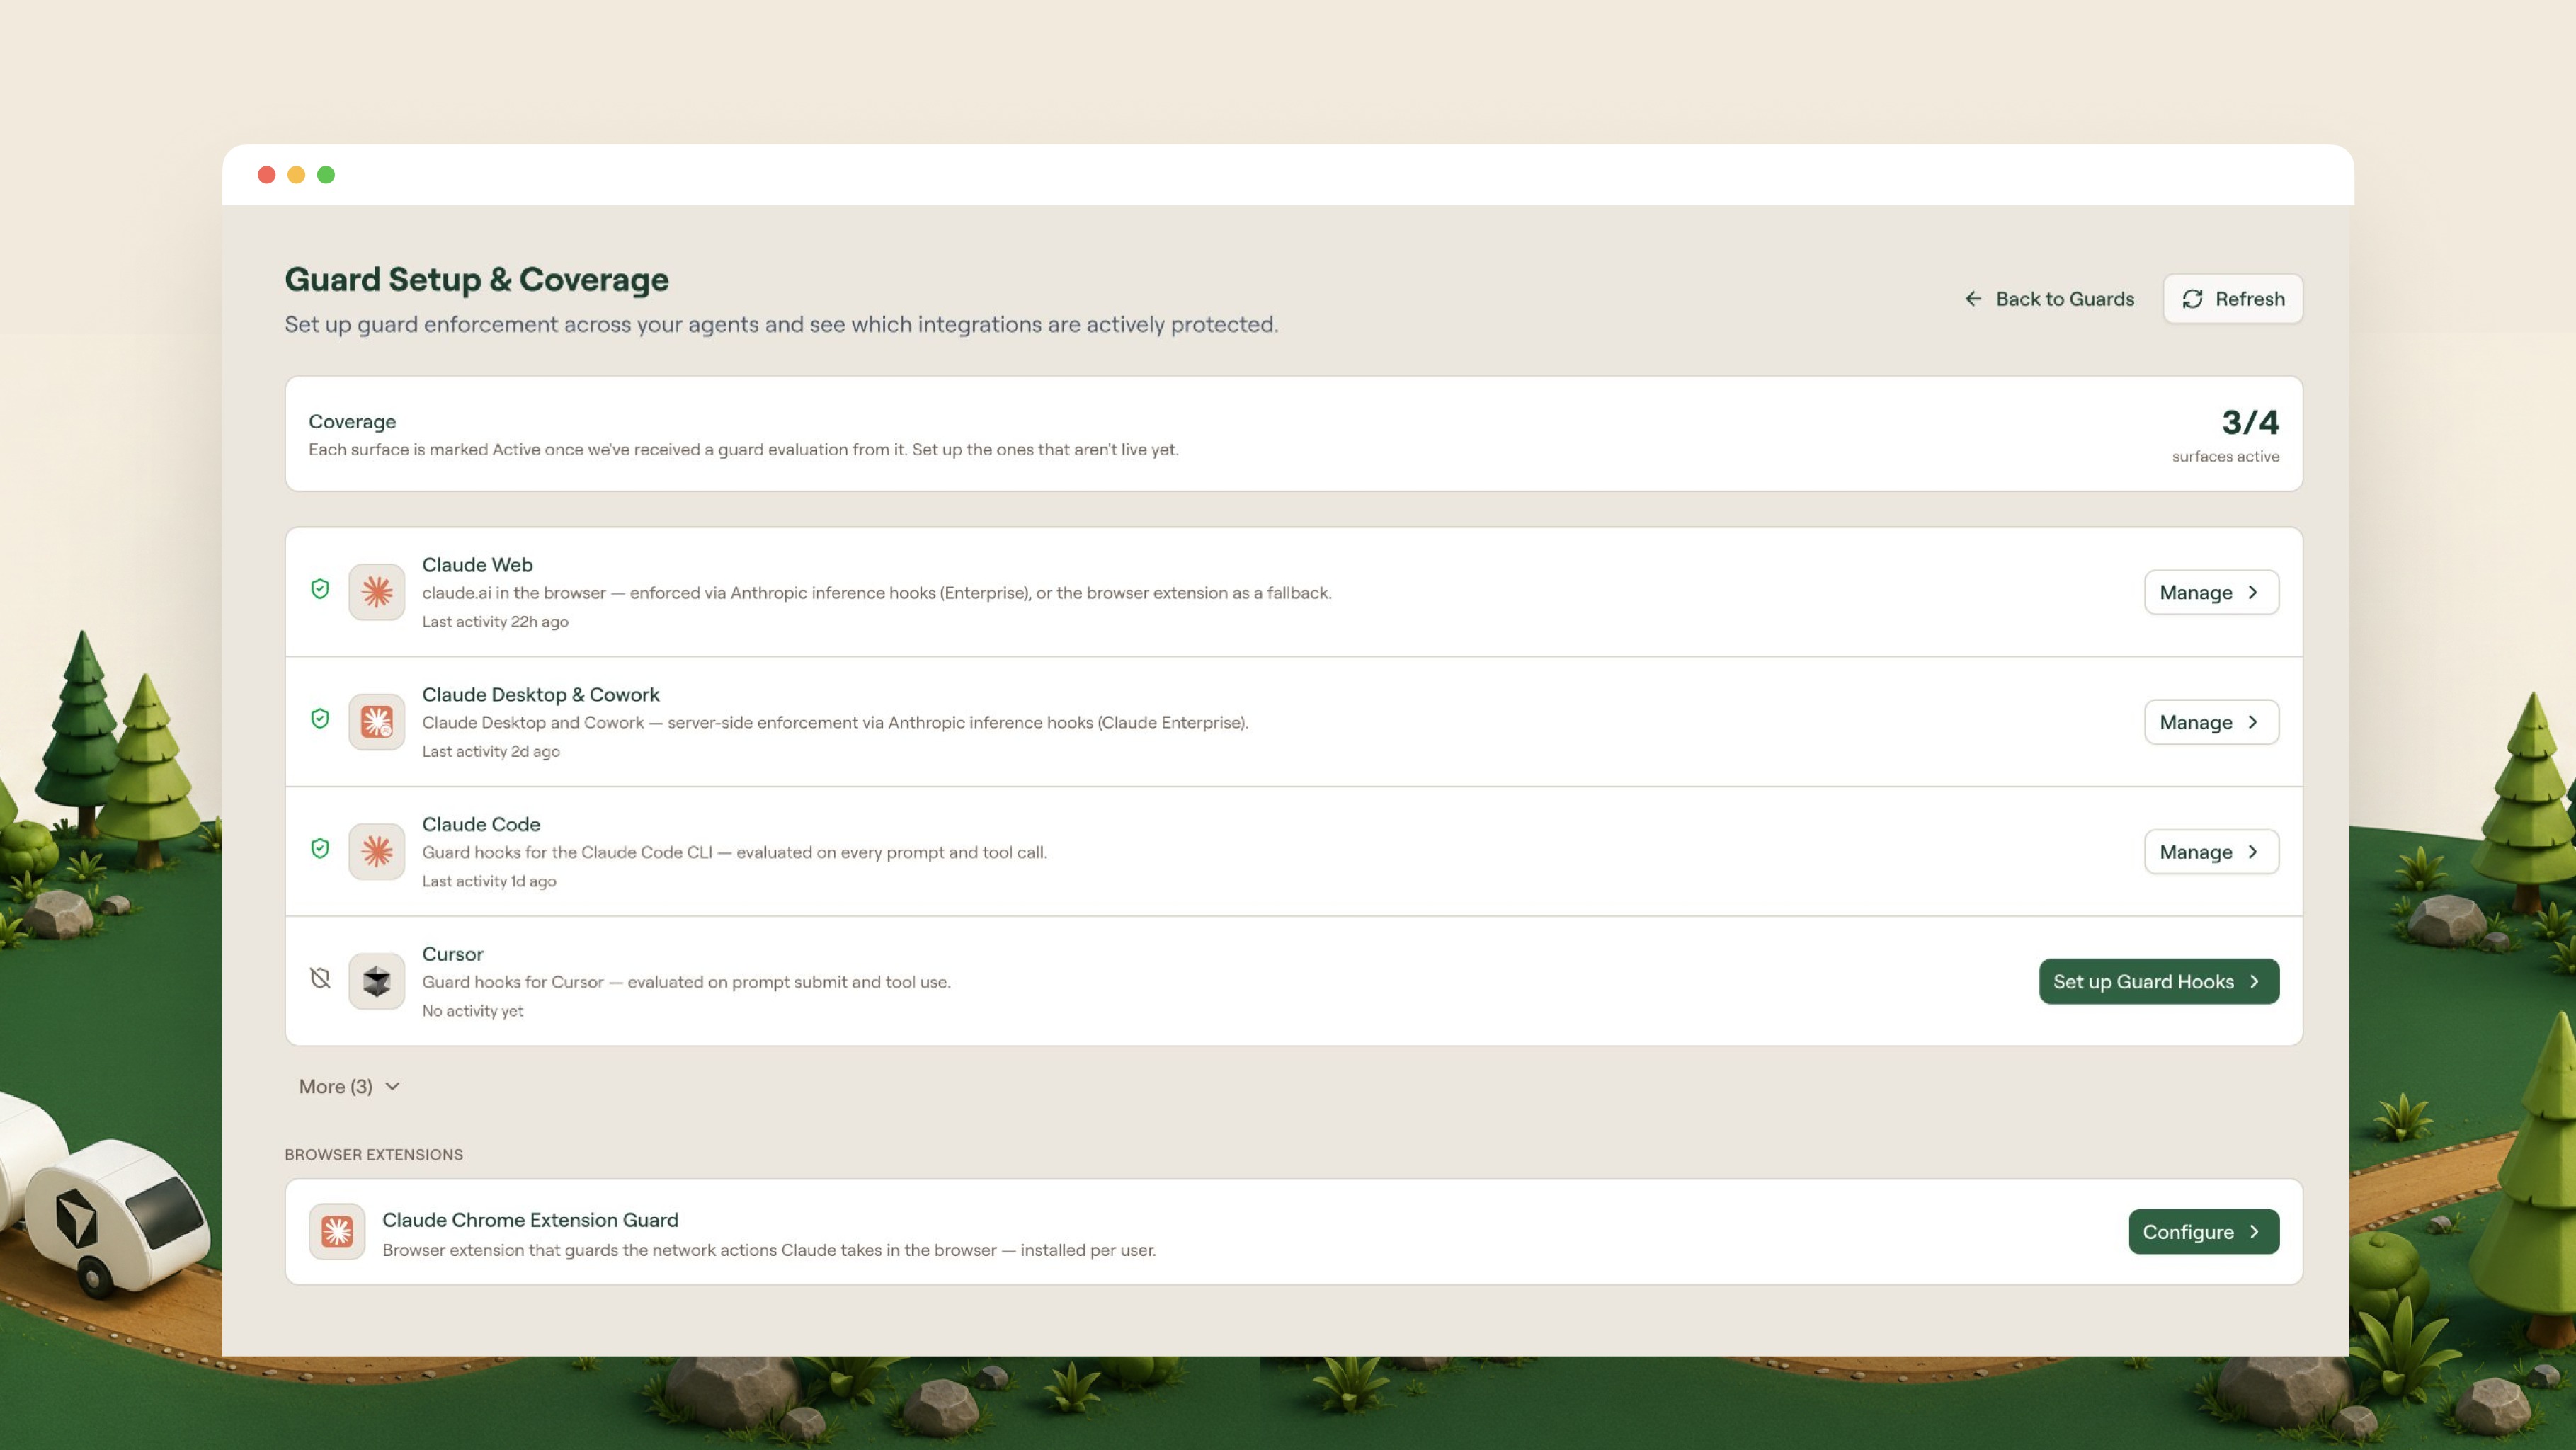
Access to each MCP server is now something you scope, not something you assume. Not every assistant needs to touch every system, but until now connecting a server exposed it to everything by default. You can now set an allowlist of AI tools per MCP server, and the gateway rejects any call from a tool that isn't on it before the request ever lands. One connector, only the tools you meant to expose, configured per server in seconds.That principle, agents get exactly what they need and nothing more, runs through the next two releases as well. Scope an MCP server
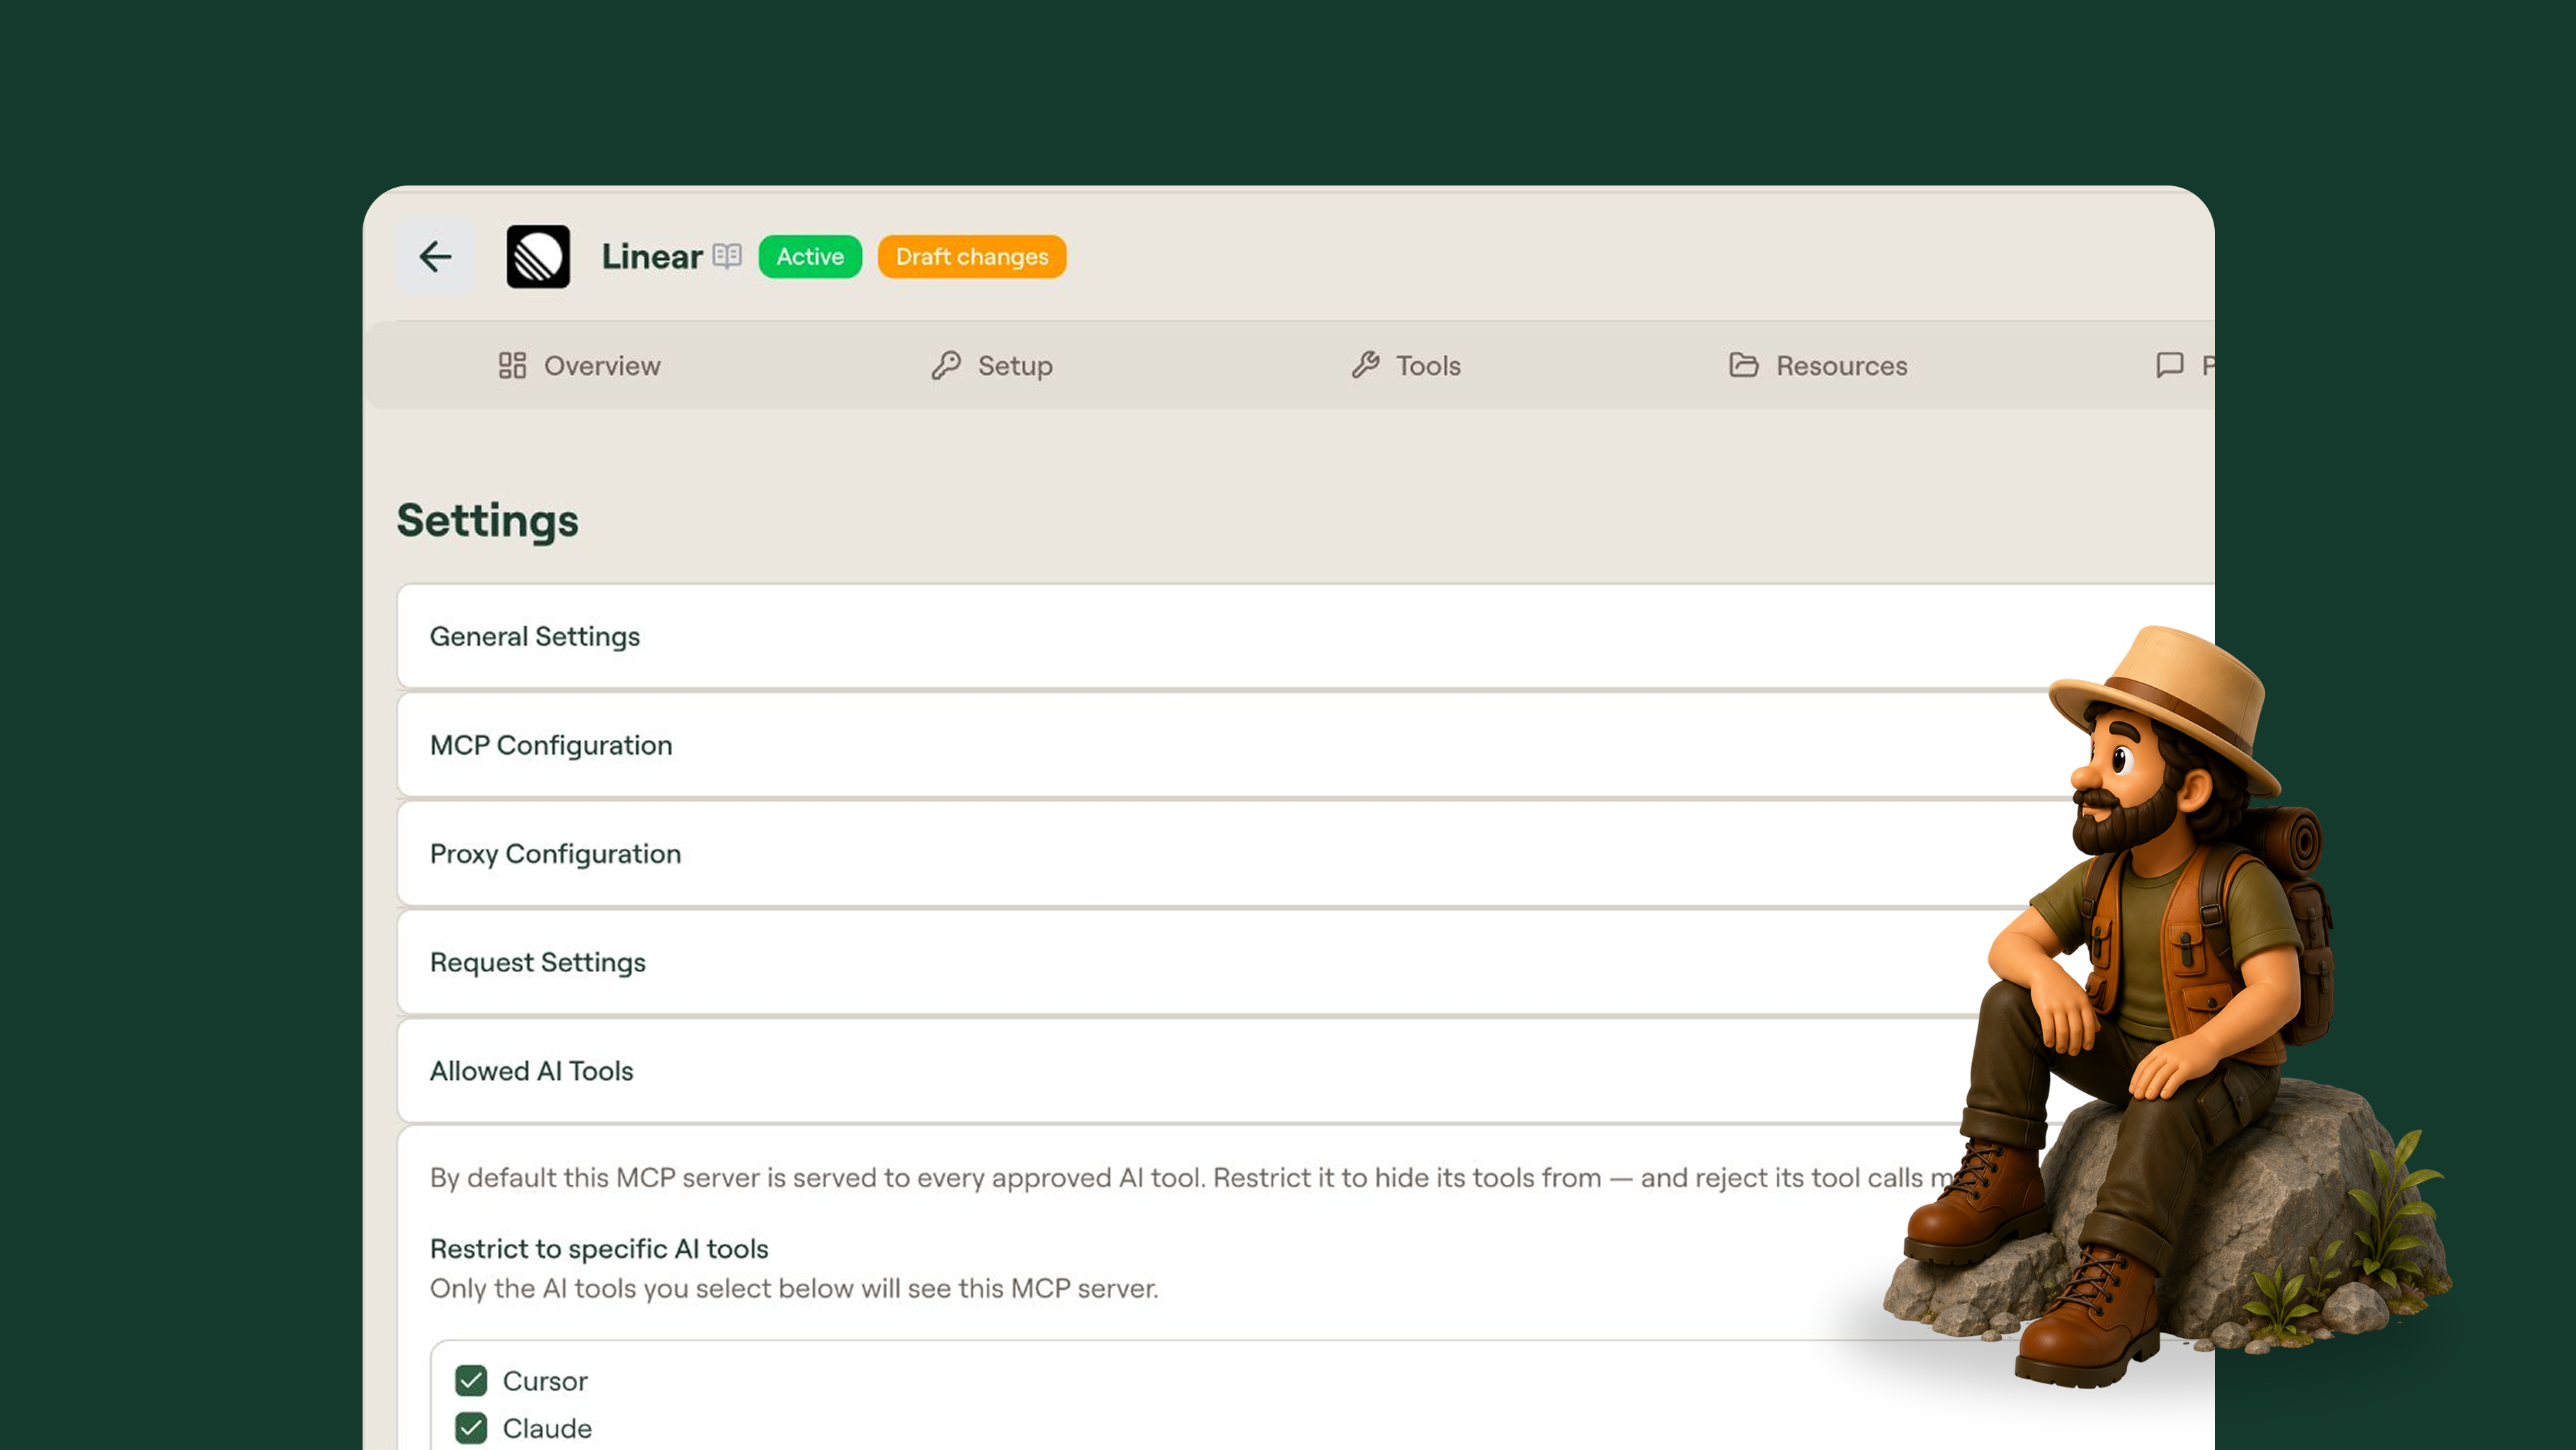
Background agents can hold their own credentials. The re-auth loop is over. Instead of borrowing a person's connection and stalling the moment it expires, an agent now authenticates per integration on its own identity, so no one has to reconnect a tool on its behalf. Point it at the MCP server default, a connected account, or its own custom key, including custom API tools, set the identity once, and it runs unattended from there. Give an agent its own credentials
Identity risk now decides what an agent can do. Access should react to risk in real time, not wait for a manual review that happens after the fact. User risk scores now sync directly from CrowdStrike and feed your guard conditions, so a flagged identity gets tighter limits the moment its score climbs. The signal your security team already trusts becomes the signal that gates the agent working on that user's behalf. Set your first risk-based guard

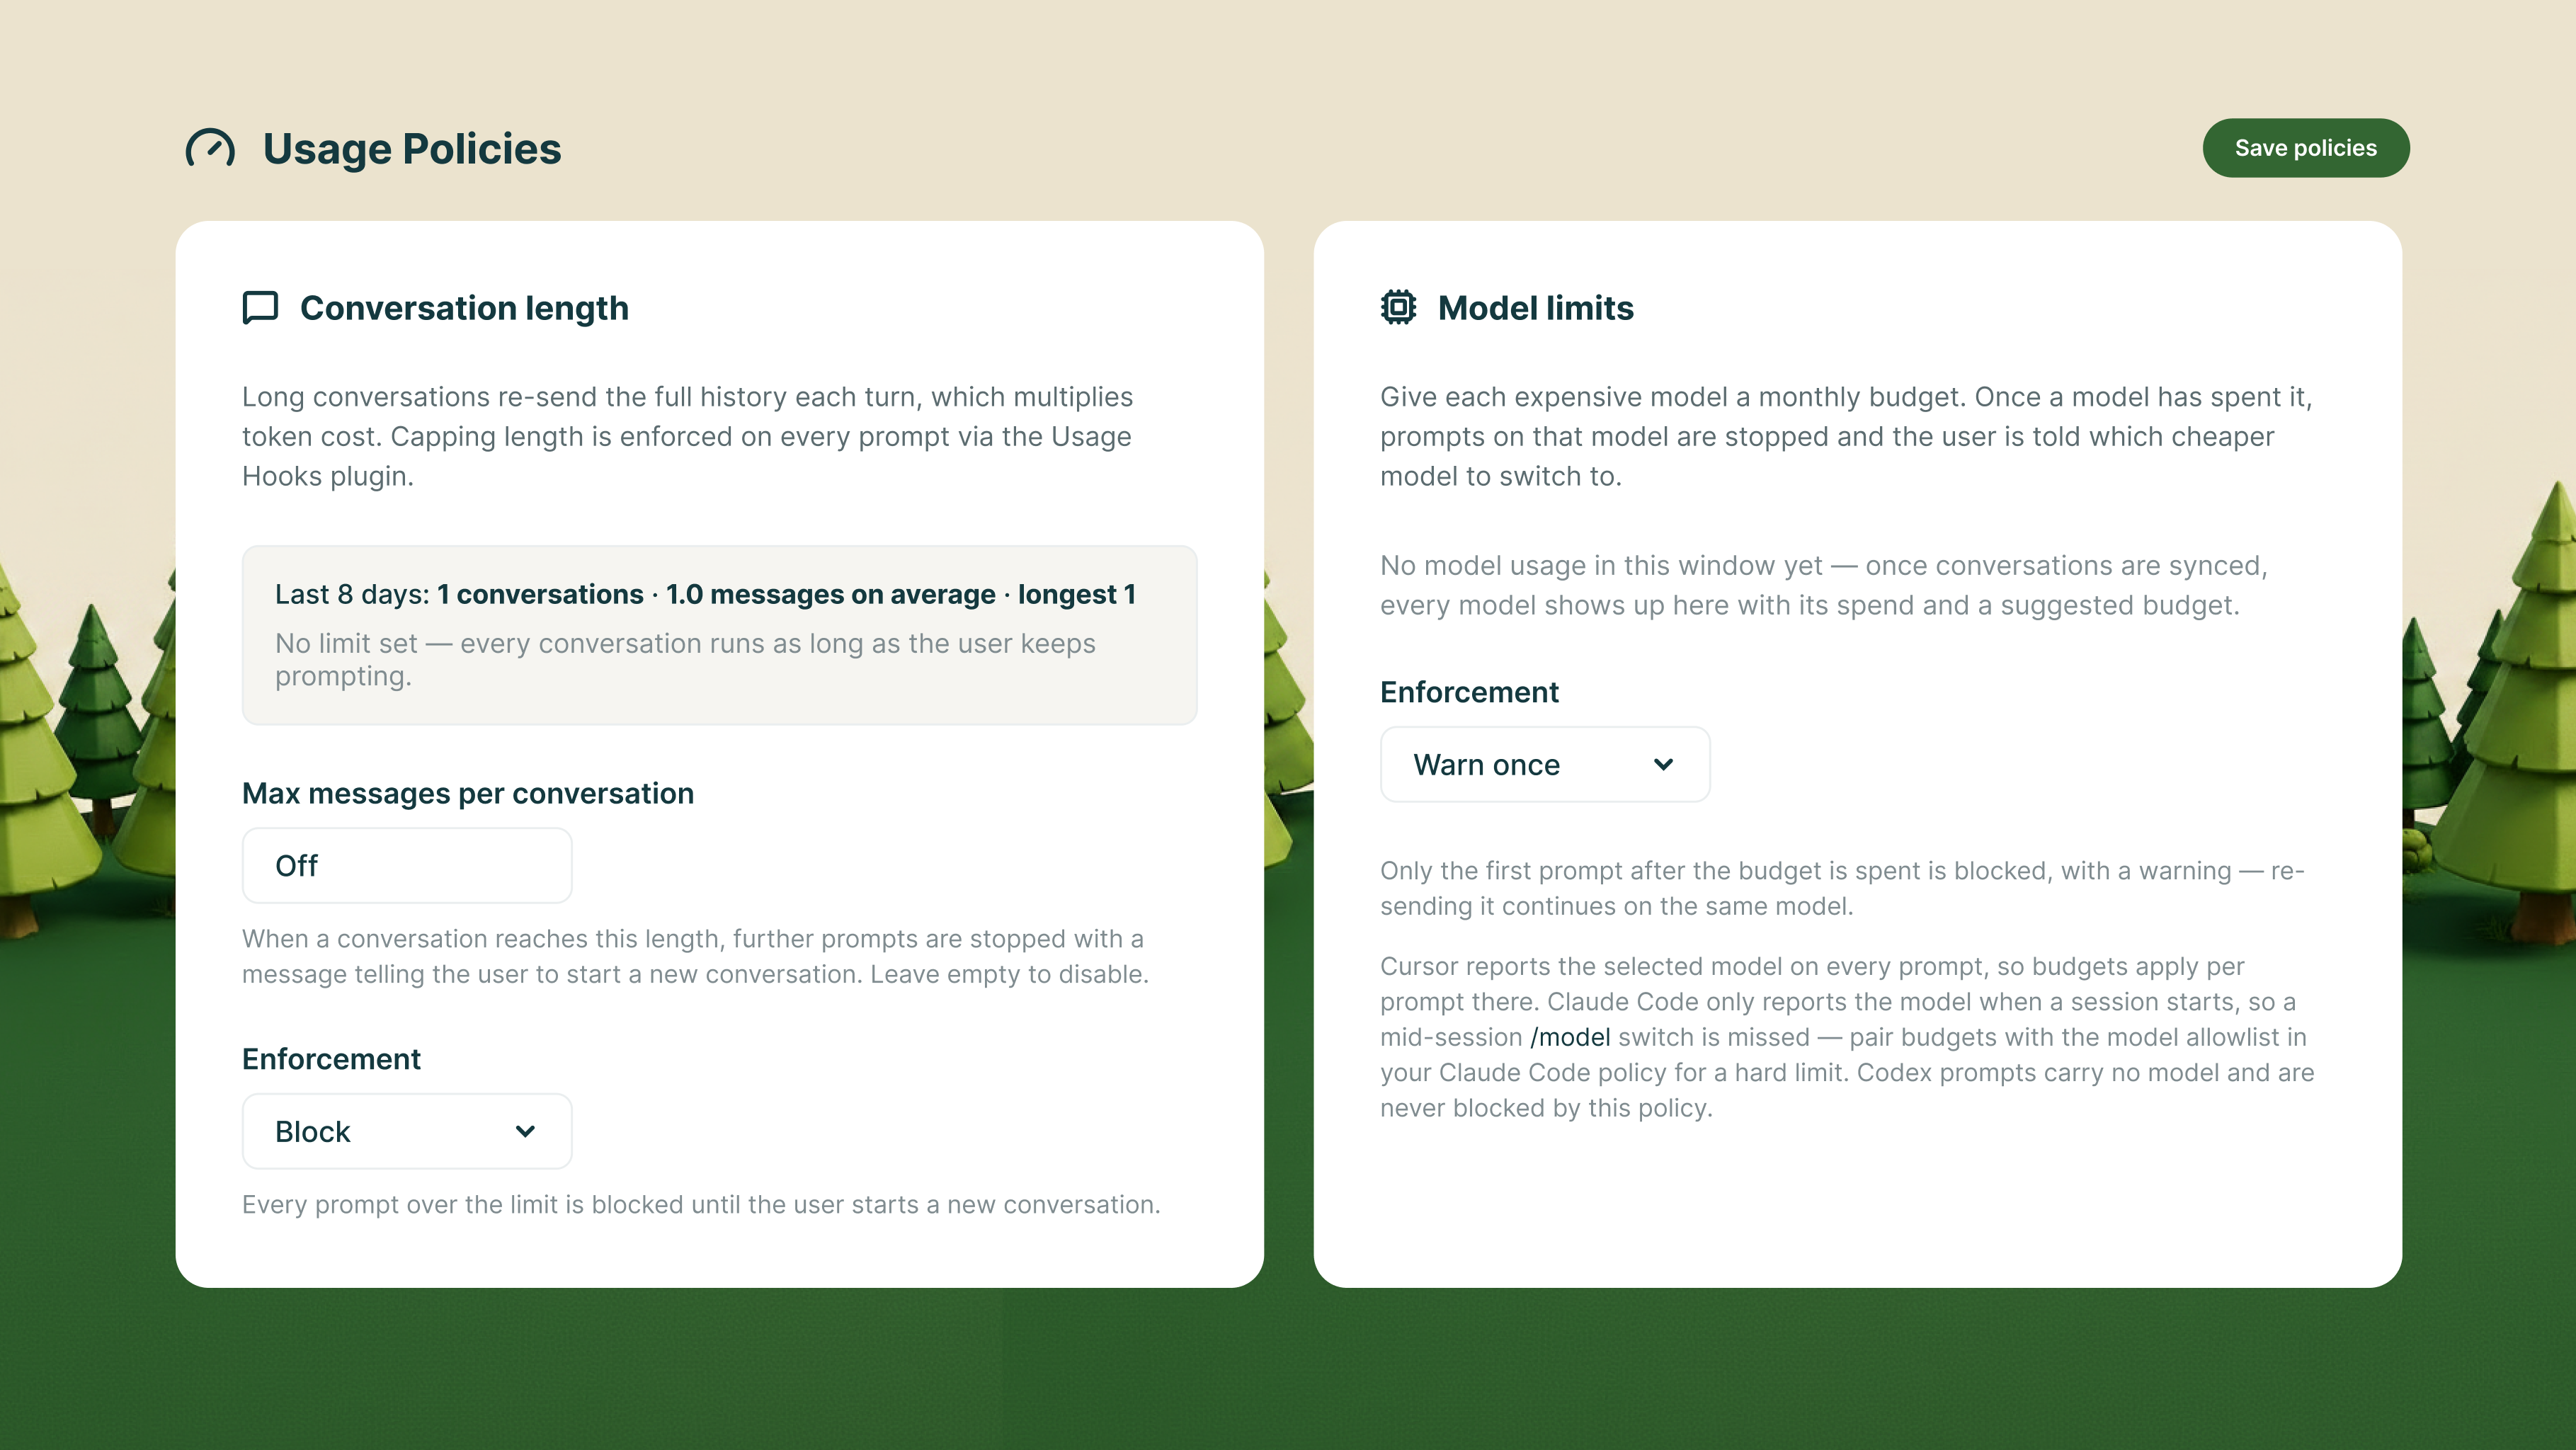
Token spend is now a ceiling you set, not a number you find on the invoice. Runaway usage used to surface after the bill did. Now you define per-model and per-conversation budgets once, and the Willow Usage Hooks plugin enforces them client-side across Claude Code, Cursor, and Codex. The Tokens page splits into three views, Dashboard, Analytics, and Optimize, so you can see the spend and cap it from the same place. Set a usage policy
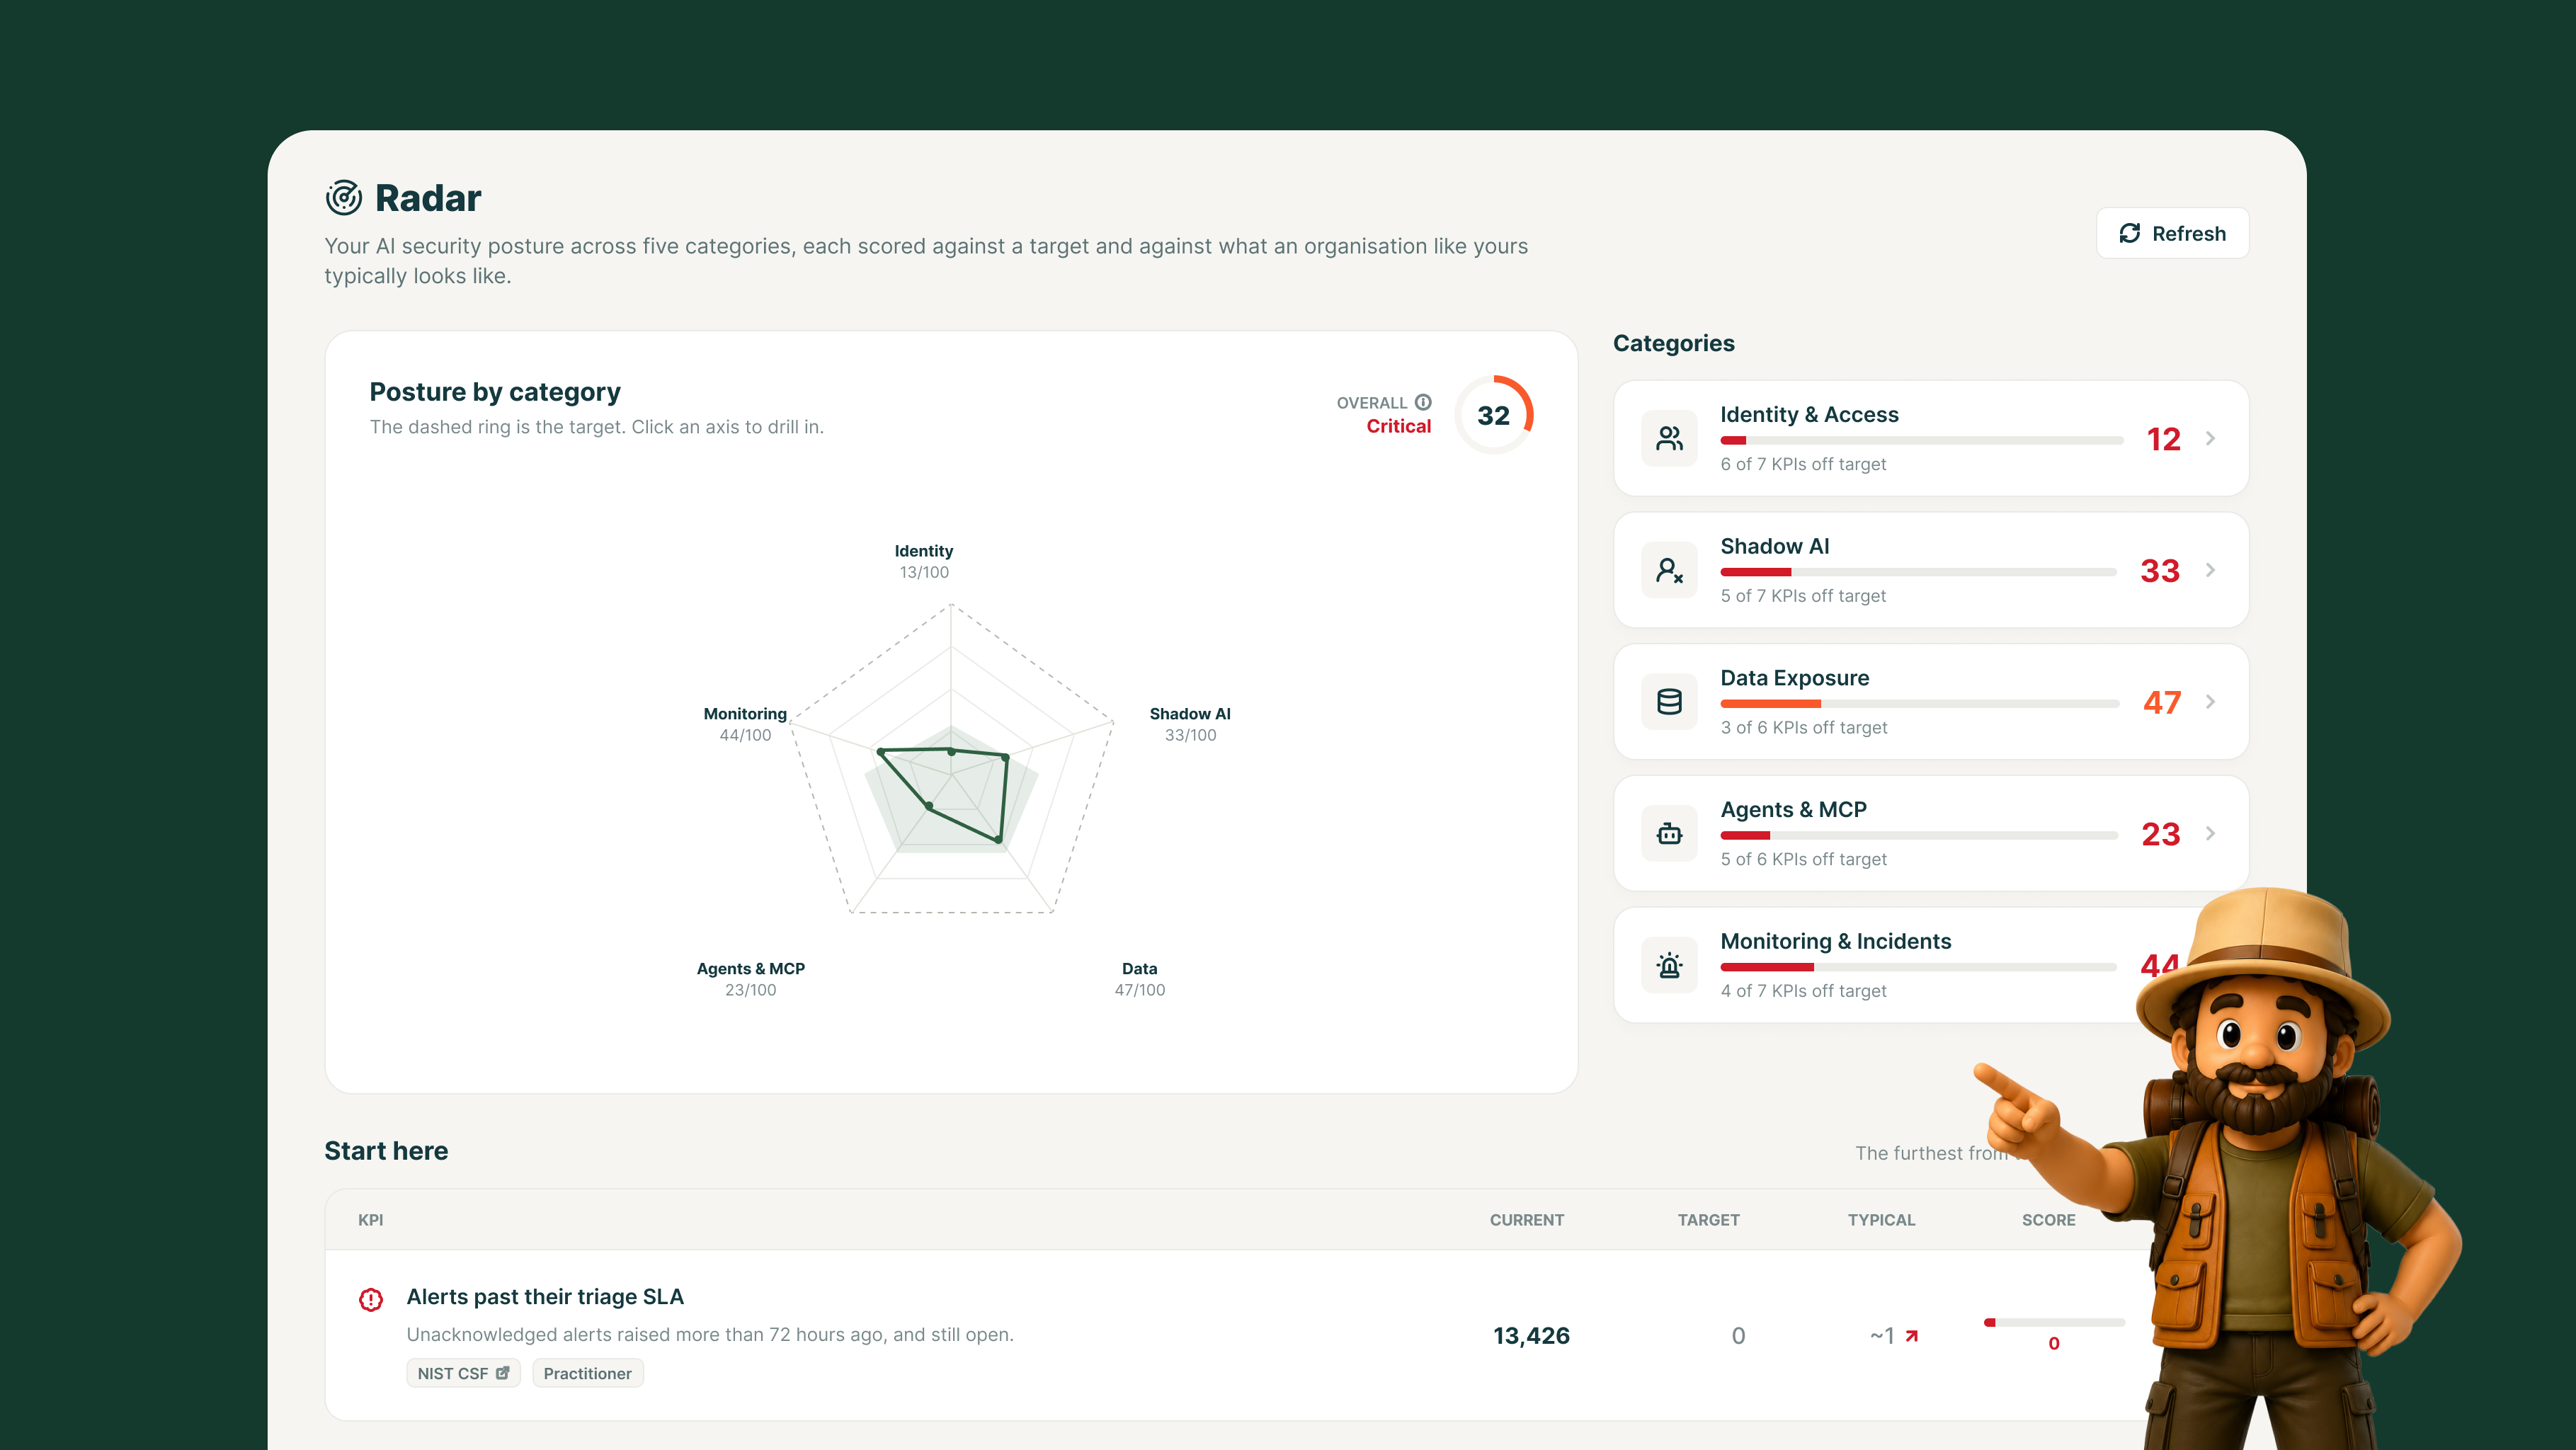
Radar is now a scorecard, not a spreadsheet exercise. Tracking your AI security posture shouldn't mean assembling the picture by hand every time someone asks. Radar now scores five categories against a target and against your peers, and hands you a start-here list ranking whatever's furthest off track. Drill into any entity for the detail behind its score, and coverage caveats flag where the underlying data is still thin, so the number never claims more certainty than you actually have. Open your Radar scorecard
Also shipped this month: Cursor Cloud Agents now run as background agents, so their branch pushes and pull requests fall under the same governance as every other agent, with no separate lane for cloud-run work. Willow also got a design refresh, including a redesigned admin dashboard that brings adoption, usage, and security onto one screen.
New to watch and read
A few things worth your time if you haven't seen them yet:
- Eyal on why token spend is a security signal, not just a line on the invoice (6 min read).
- Shalev on the shadow AI already inside your org, and what to actually do about it (9 min read).
- Eyal's field note from Black Hat 2026, on why governing AI agents beats banning them (1 min).
- And Eyal on how to stop paying for the tokens your agents waste (1 ).
The through-line
The pattern under all of it is the same one from July, pushed a step further. The old tradeoff was block a capability or trust it. This month's work is about letting agents run on their own without that being the same thing as letting them run unchecked. More autonomy on one side, more control on the other, set as policy rather than left to hope.
Questions on anything above? Just reply, we read every one.
Keep building. The Willow Team
Background Agents in the Enterprise
Most teams can spin up an agent. Few can deploy one their security team signs off on. Here's the framework that does both.
FAQS
Everything you need to get your Basecamp running.


Your agents are already in the wild.
Give them a Basecamp. Go from AI chaos to AI work, in minutes.
